
BharatGPT Beats a Model 15x Its Size. Data Stays Sovereign.
We ran the numbers on BharatGPT against the open-weight models everyone keeps citing, Qwen and Sarvam. Here is what we found, including the parts that make us look good and the one part that does not.
Small Model. Big Win.
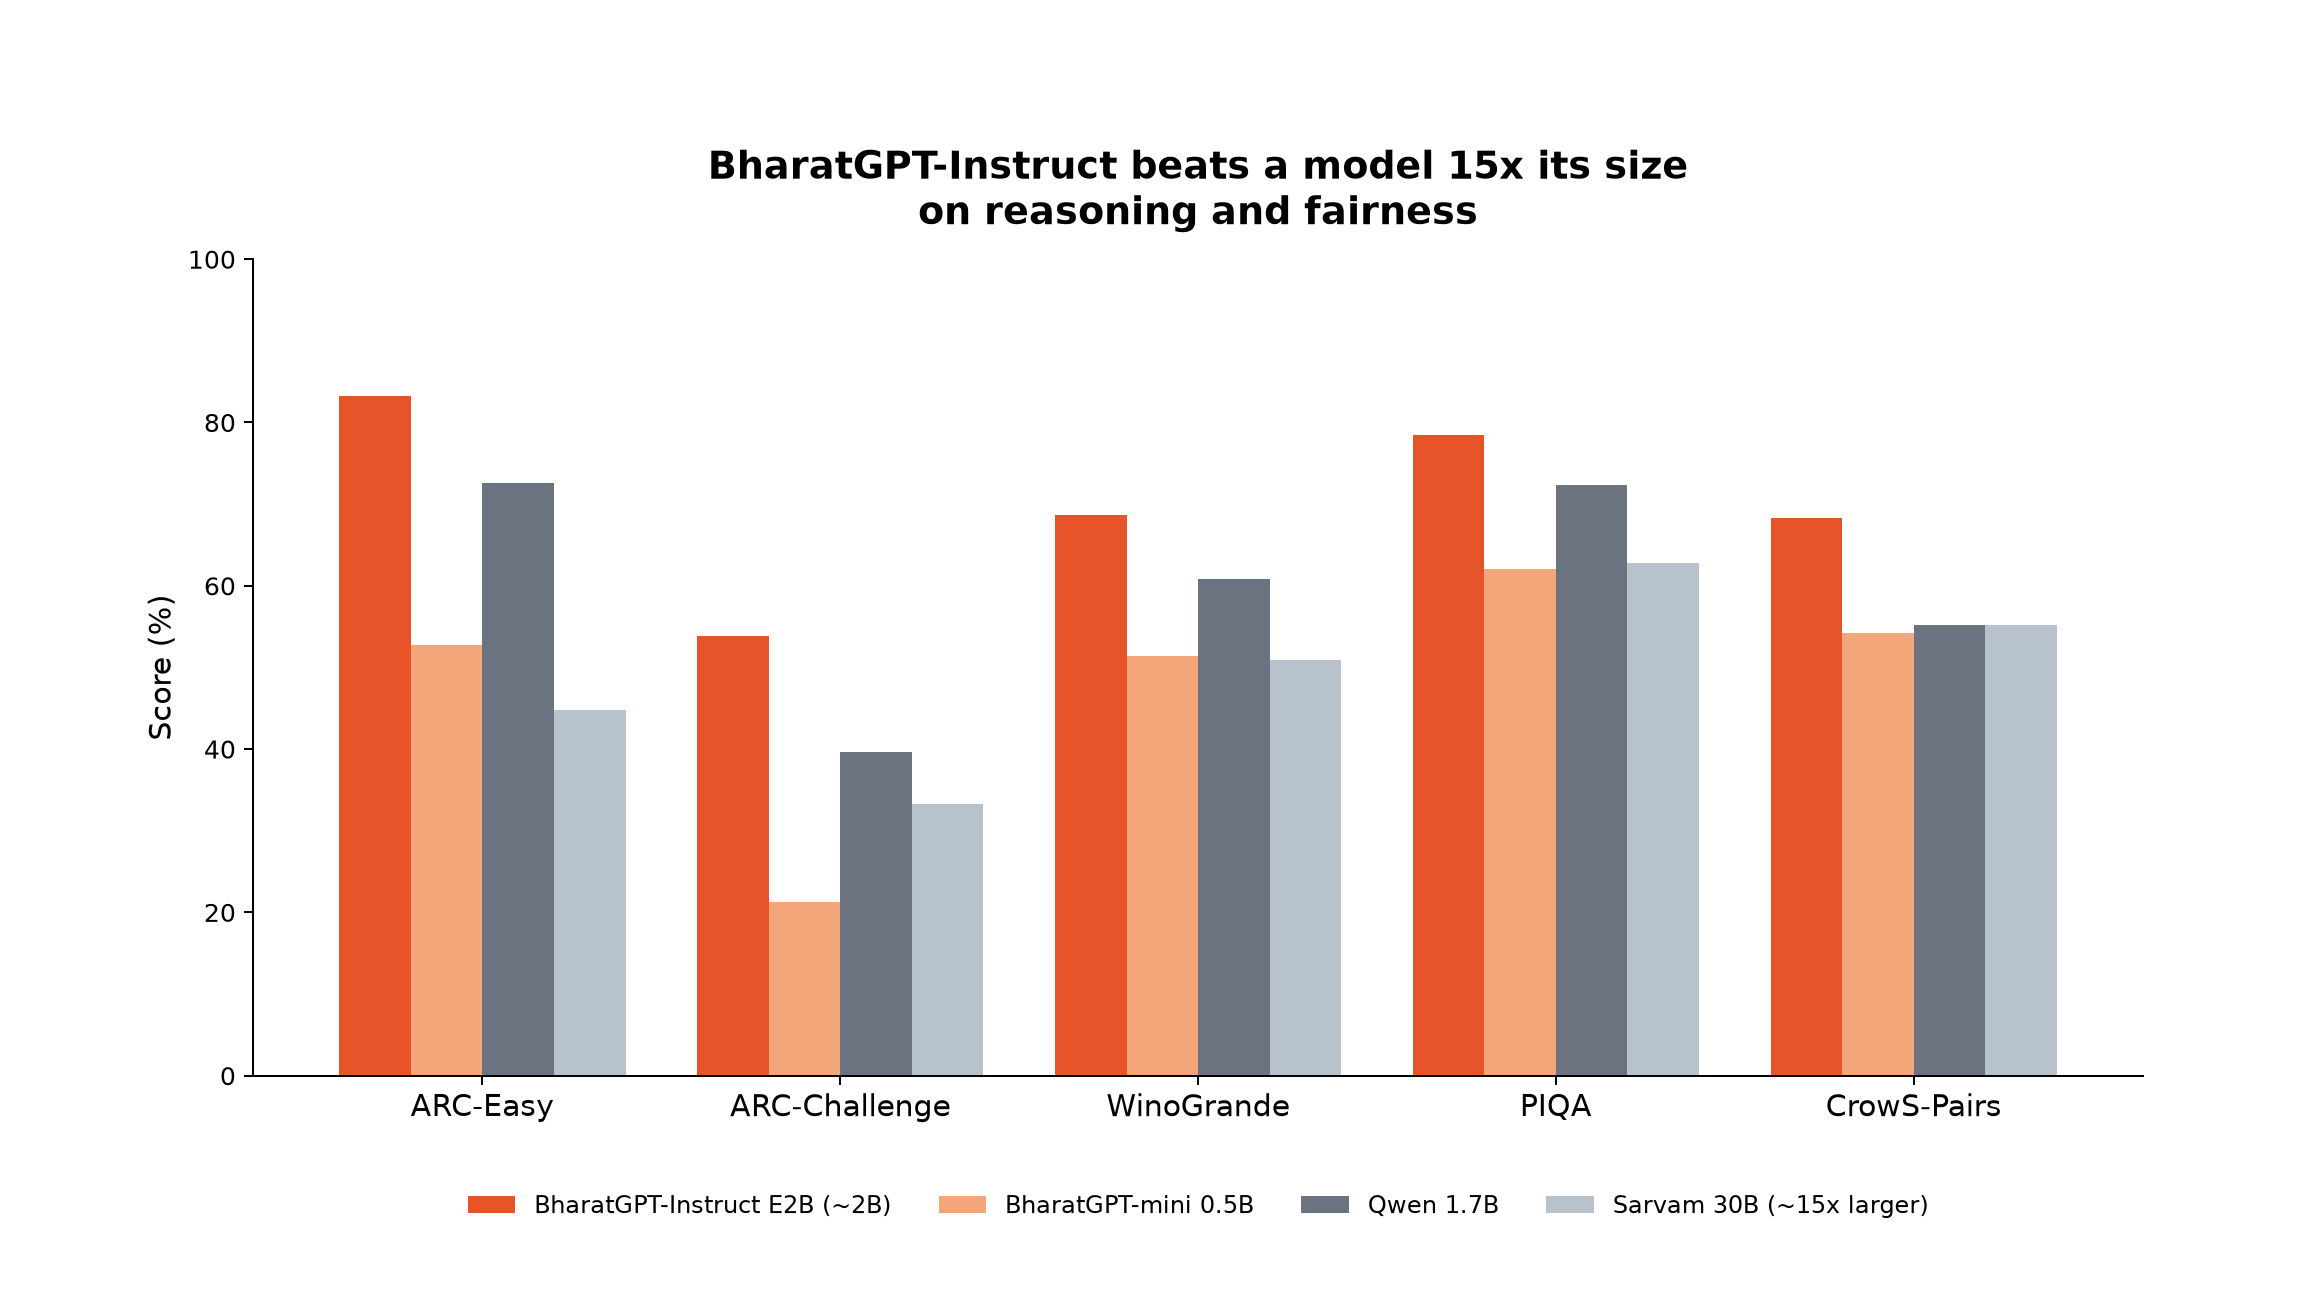
BharatGPT-Instruct is roughly 2 billion active parameters. Sarvam 30B is roughly 15 times larger. On science reasoning, commonsense reasoning, and fairness, BharatGPT wins anyway.
- ARC-Easy: 83.21% vs 44.80% (Sarvam 30B), 72.60% (Qwen 1.7B)
- ARC-Challenge: 53.84% vs 33.30% (Sarvam 30B), 39.70% (Qwen 1.7B)
- PIQA: 78.51% vs 62.80% (Sarvam 30B), 72.40% (Qwen 1.7B)
- CrowS-Pairs (fairness): 68.28% vs 55.20% (Sarvam 30B), 55.20% (Qwen 1.7B)
BharatGPT-mini sits below all three here, and that is by design. Unlike models fine-tuned on top of an existing base, mini is a foundational model, built from scratch, at just 538 million parameters, less than a third of Qwen 1.7B and a fraction of Sarvam 30B. It is not built to top a reasoning leaderboard. It is built for on-device and edge deployment, where every megabyte and every millisecond counts.
The Full Picture, Not Just the Highlights
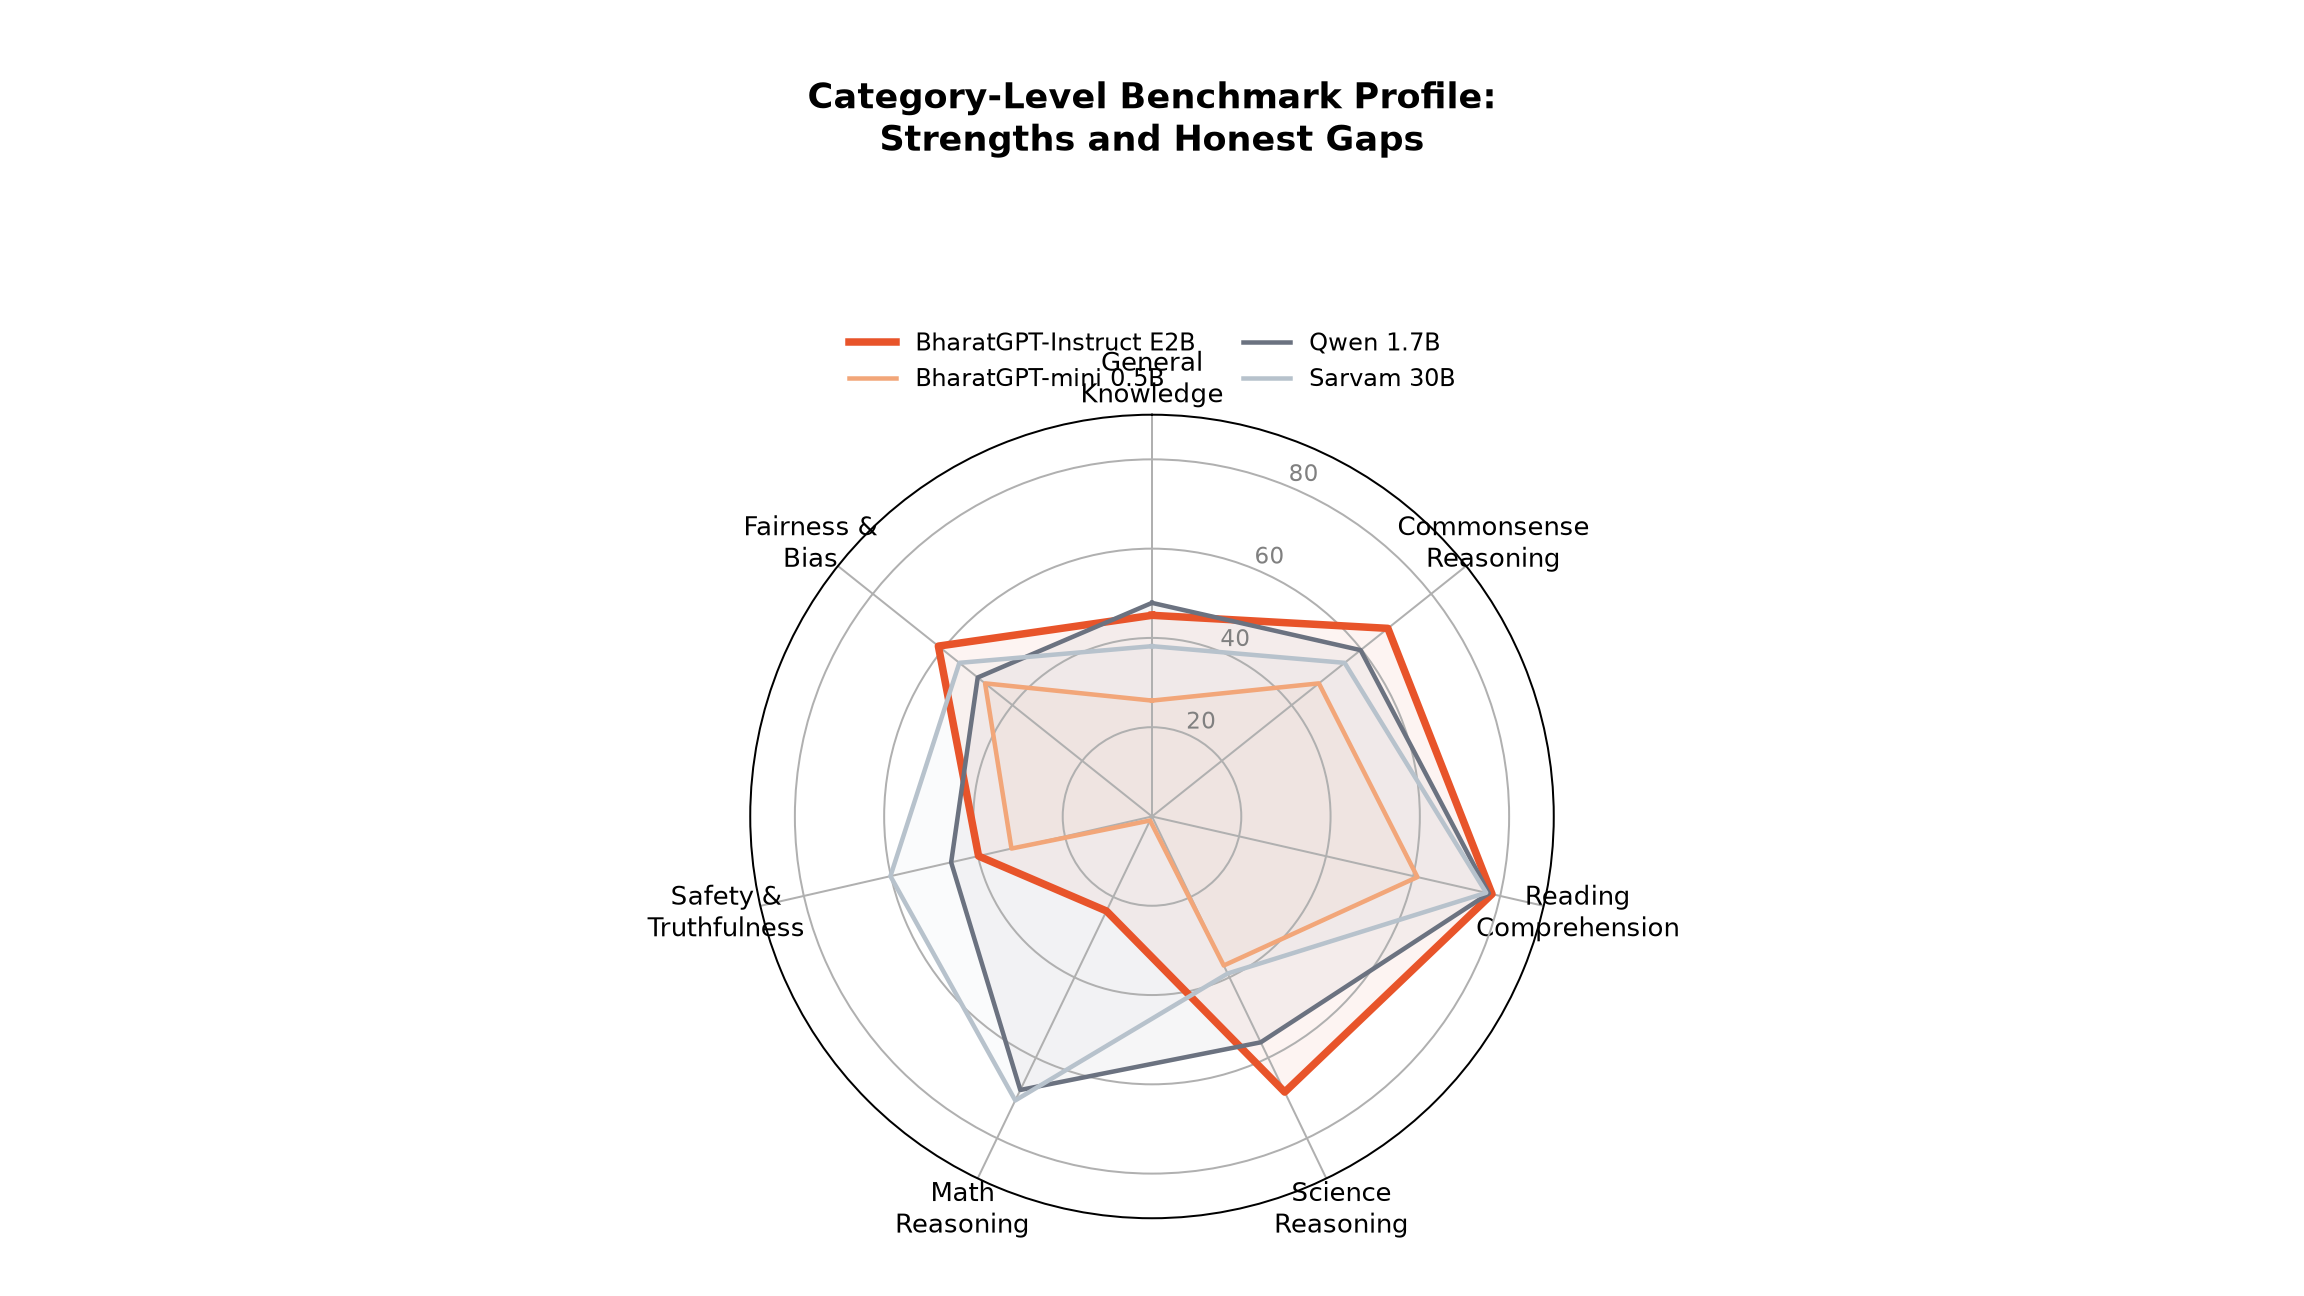
Cherry-picked benchmarks are easy. A full profile is harder, and more honest. Across seven benchmark categories, BharatGPT-Instruct leads or holds parity on general knowledge, commonsense reasoning, reading comprehension, science reasoning, and fairness. Math reasoning is a real gap today, GSM8K sits well behind Qwen 1.7B and Sarvam 30B, and that is exactly the kind of number we would rather publish than hide. It tells us, and you, where the next release needs to focus.
The Efficiency Frontier
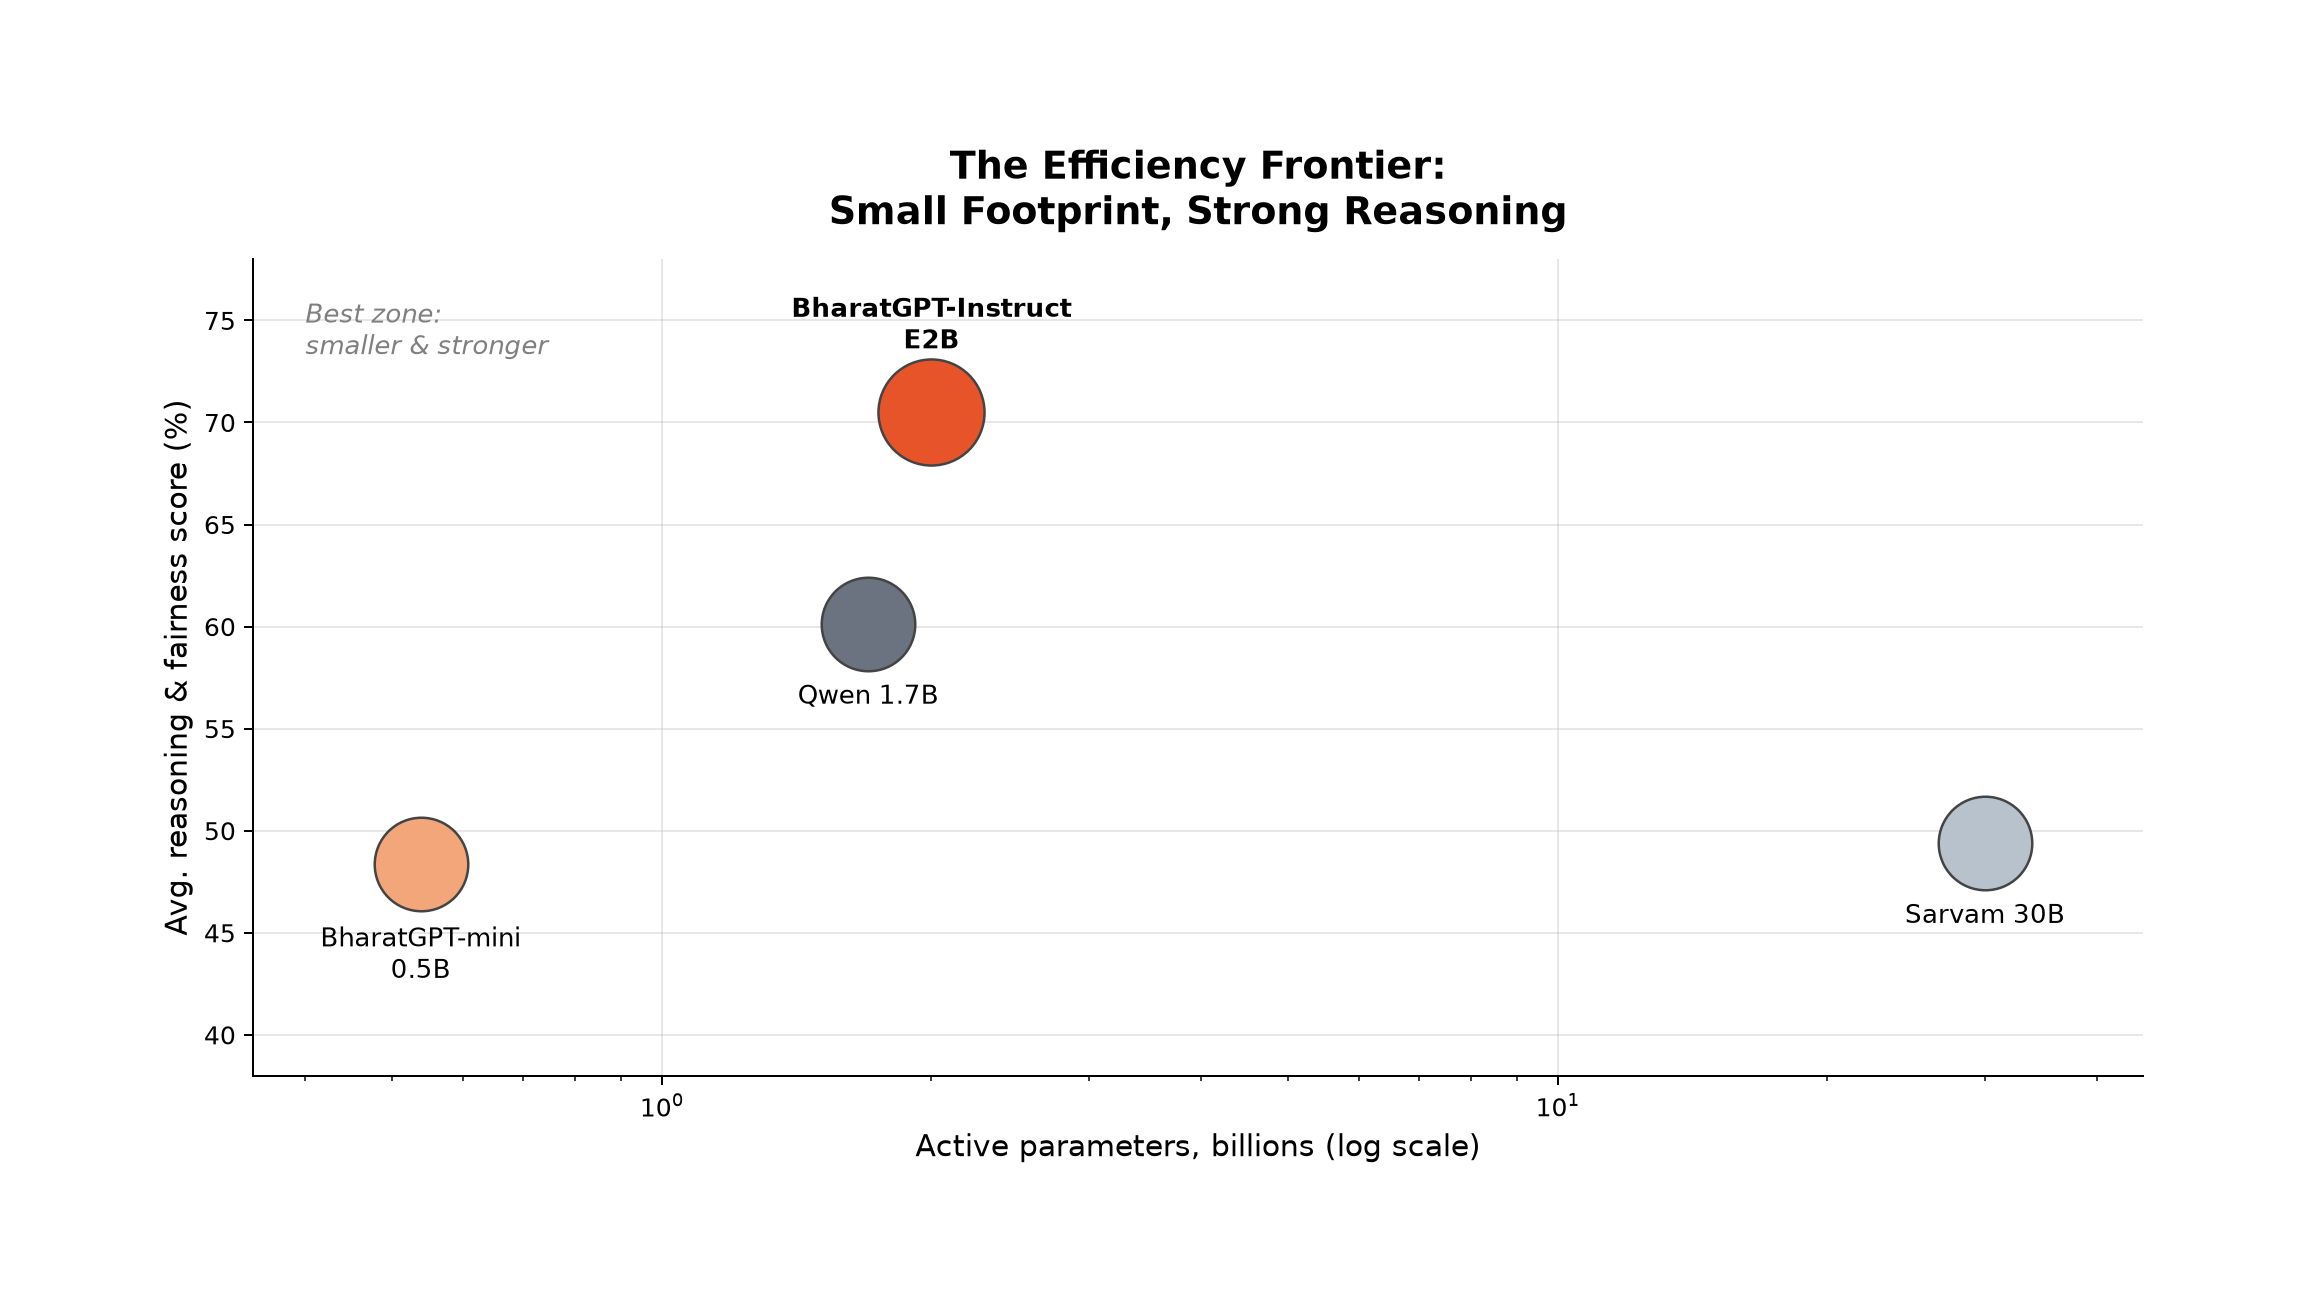
Plot reasoning and fairness performance against active parameter count, and the shape of the story changes. BharatGPT-Instruct sits in the top-left, the smaller footprint, higher score zone, ahead of Qwen 1.7B and well ahead of Sarvam 30B despite Sarvam carrying roughly 15 times the parameters. BharatGPT-mini sits where a 538-million-parameter edge model should sit: modest on raw score, but doing more with less than its size would suggest.
Every Regional Language. Not Some.
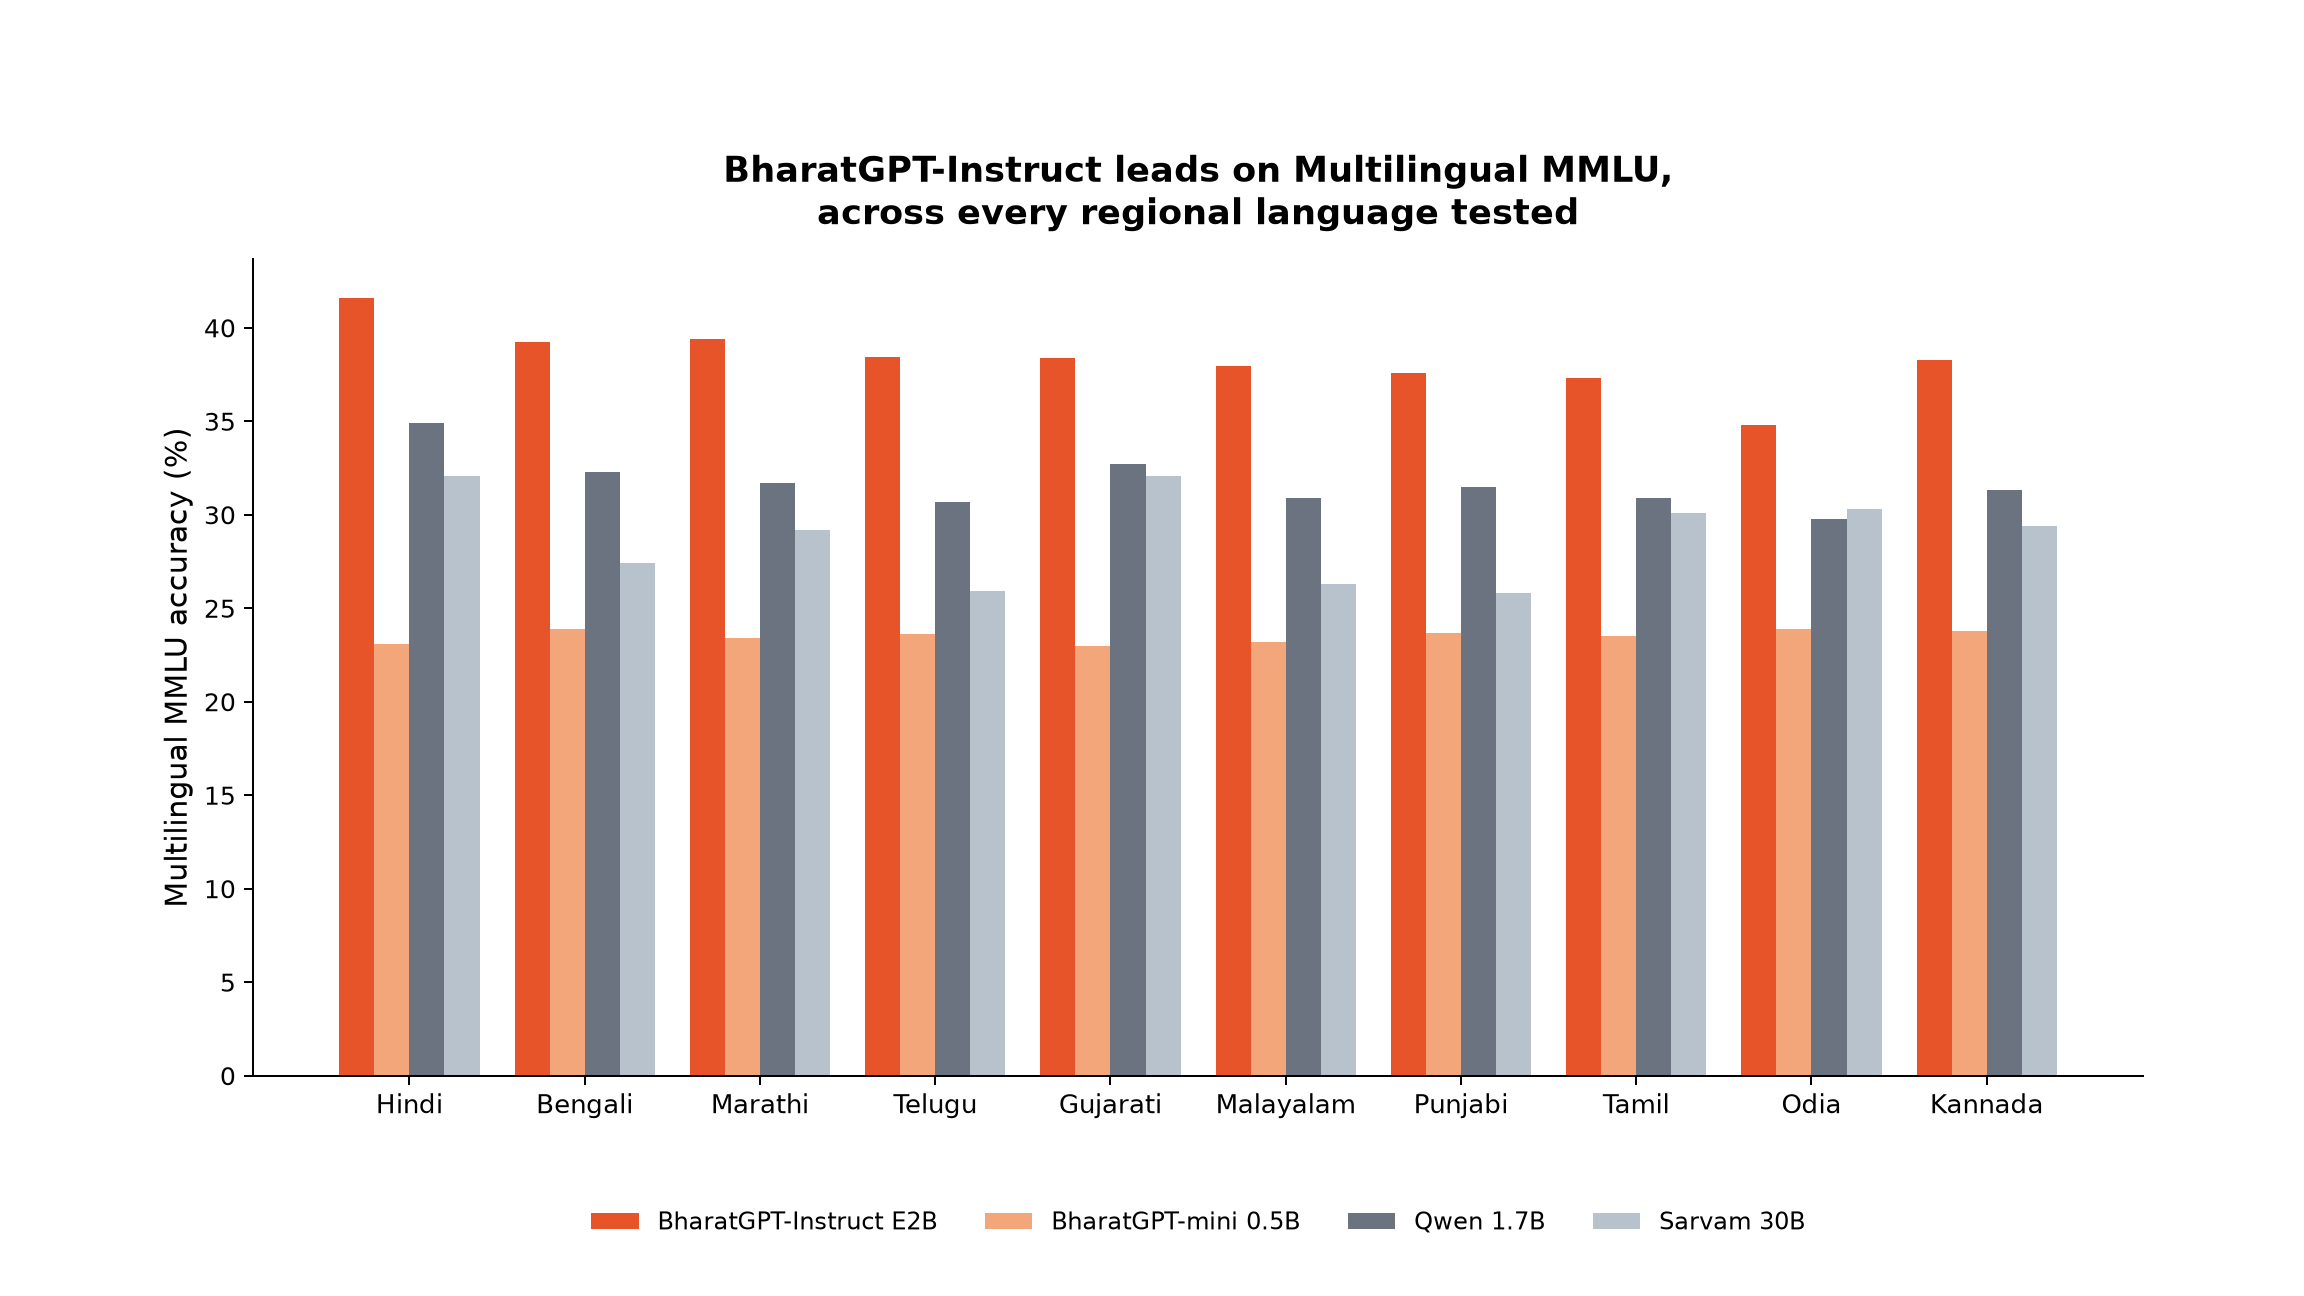
Multilingual capability gets claimed a lot. It gets proven rarely. We tested Multilingual MMLU across ten regional languages. BharatGPT-Instruct leads Qwen 1.7B and Sarvam 30B in all ten. Hindi, Bengali, Marathi, Telugu, Gujarati, Malayalam, Punjabi, Tamil, Odia, Kannada. Every one.
BharatGPT-mini trails the pack here too, consistent with its role as the lightweight, low-resource-language option rather than the reasoning flagship.
Benchmarks Are Nice. RAG Is the Business.
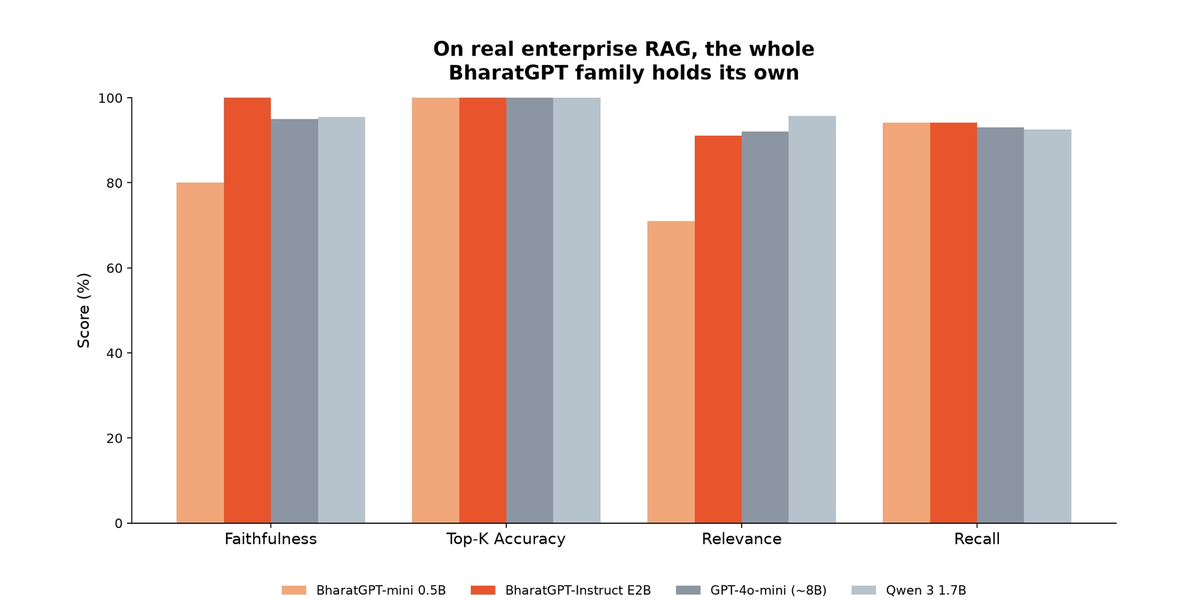
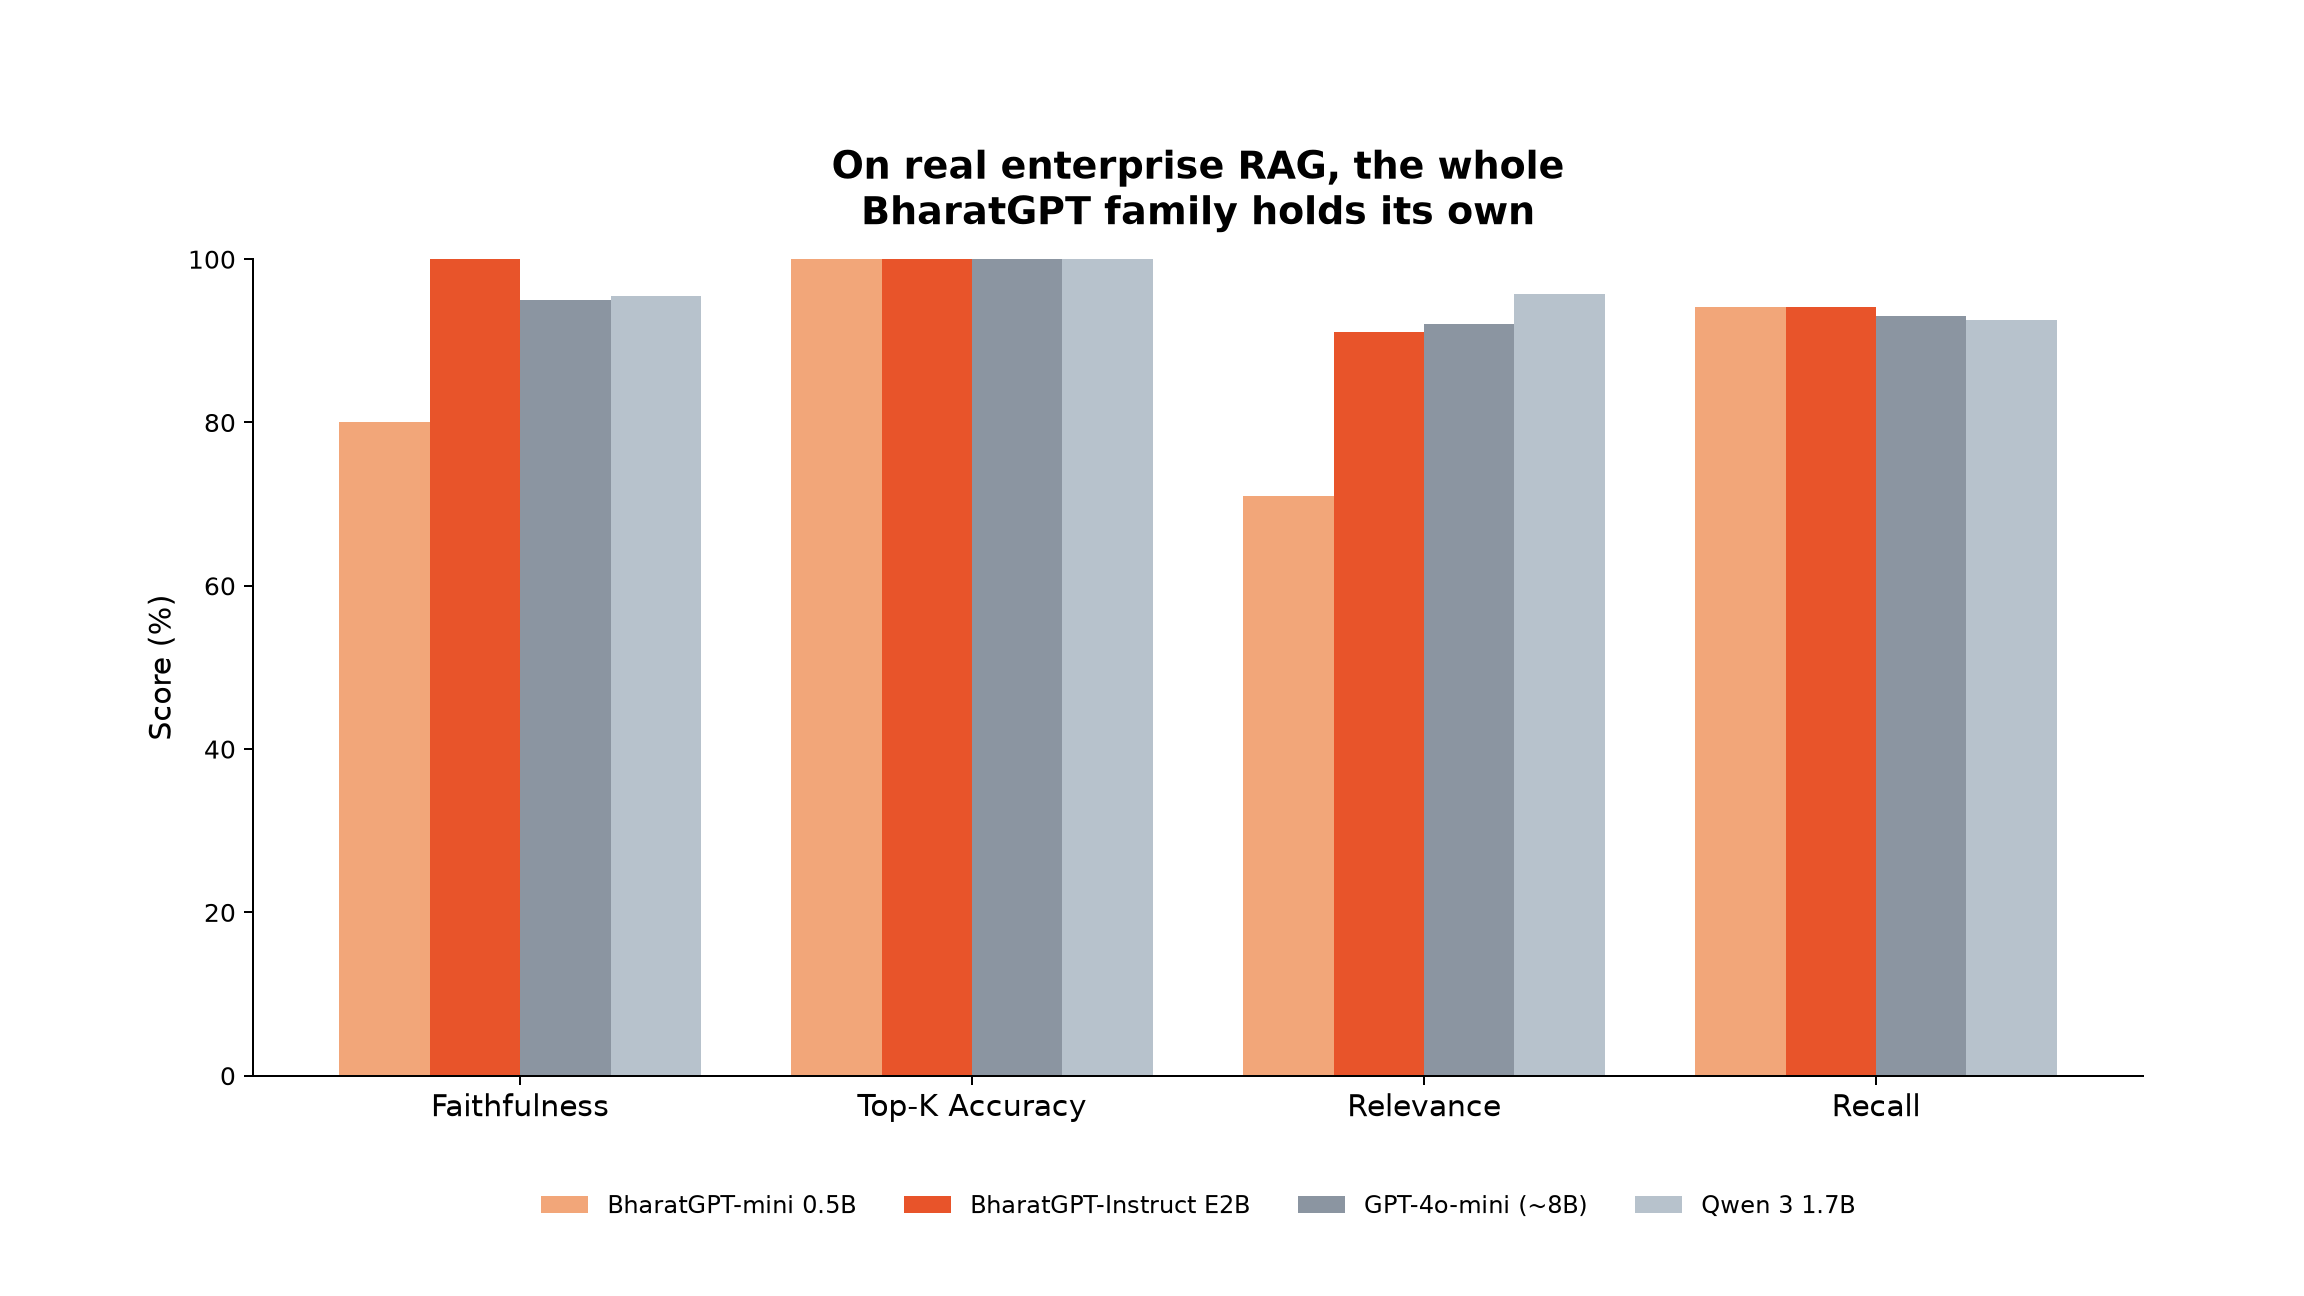
Here is the number that actually matters for our enterprise AI Assistants: faithfulness on retrieval-augmented generation, grounded in a customer's own knowledge base. BharatGPT-Instruct scores 100.00% on Faithfulness. GPT-4o-mini scores 95.00%. Qwen 3 1.7B scores 95.51%. On Top-K Accuracy, all three tie at 100%. This is near-parity with frontier-adjacent models, on the metric closest to what our clients actually deploy. Even BharatGPT-mini, our smallest and fastest model, scores 80.09% on Faithfulness and ties everyone at 100% on Top-K Accuracy. That is a lot of grounded accuracy for a model built to run on-device.
We Process Data. We Do Not Own It.
Enterprises keep asking us one question. Does CoRover own our data, or only process it? The answer is simple. We process it. We never own it. Every dataset that enters BharatGPT training passes a four-step check: source and license verification, right-to-train and contractual review, PII filtering and anonymisation, and quality and deduplication. For sensitive institutional and regulated partners, we run a strict no-training, deployment-only policy. Their data never touches a training run.
Learnings can cross-pollinate, generalised and anonymised, into the base model. Client data never does. We transfer learnings, not data. That distinction is the whole point.
Built for Enterprise Security
Sovereignty without security is a slogan. We treat both as engineering requirements, not marketing lines.
- Tenant isolation: strict, per-tenant data boundaries with role-based access control.
- Encryption end to end: data protected in transit and at rest, passwords never stored in plain text.
- PII and compliance: automated detection and filtering of personally identifiable information, with regulatory compliance built into the pipeline.
- Prompt injection and content filtering: guardrails against adversarial inputs, SQL and XSS filtering built in.
- Audit logs and observability: every response traceable, every decision explainable, for full audit readiness.
Scale is not the same as intelligence. Models built for the country, from 0.5 to 2 billion parameters, just outreasoned a model fifteen times their size. That is not an accident. That is what happens when you build for the problem instead of building for the leaderboard.
— Ankush Sabharwal, Founder & CEO, CoRover.ai
Domain-Specific BharatGPT: Live and Expanding
BharatGPT was never meant to stop at one general-purpose model. We are now building domain-specific versions of BharatGPT, trained and tuned for the language, workflows, and edge cases of a single sector.
PortGPT, built for the shipping ports domain, is already live. More domain-specific models are in the pipeline and will ship in the months ahead.
This is the same conviction behind BharatGPT-mini: a point solution on a smaller, purpose-built model gets to production faster and performs better on the job it was actually built for, instead of chasing a generic leaderboard.
Scale That Backs the Benchmarks
Benchmarks are a lab test. This is what BharatGPT and CoRover's platform run in production, today:
- 1.8B+ Lives Impacted
- 65M+ Monthly Active Users
- 95K+ Enterprises, Developers & Researchers
Appendix: Full Benchmark Data
A1. Complete Benchmark Scores by Category
Figures are accuracy/score percentages.
| Category | Benchmark | BharatGPT-3B-Indic | BharatGPT-mini 0.5B | BharatGPT-Instruct E2B | Qwen 1.7B | Sarvam 30B |
|---|---|---|---|---|---|---|
| General Knowledge | MMLU | 52.90 | 23.60 | 57.56 | 55.50 | 45.60 |
| General Knowledge | AGIEval | 30.40 | 28.32 | 32.57 | 40.20 | 30.70 |
| Commonsense Reasoning | HellaSwag | 67.60 | 29.93 | 55.59 | 46.10 | 51.90 |
| Commonsense Reasoning | PIQA | 75.70 | 62.08 | 78.51 | 72.40 | 62.80 |
| Commonsense Reasoning | WinoGrande | 64.80 | 51.46 | 68.67 | 60.80 | 50.90 |
| Reading Comprehension | BoolQ | 78.70 | 60.98 | 78.13 | 77.40 | 76.80 |
| Science Reasoning | ARC-Easy | 73.40 | 52.78 | 83.21 | 72.60 | 44.80 |
| Science Reasoning | ARC-Challenge | 42.90 | 21.33 | 53.84 | 39.70 | 33.30 |
| Math Reasoning | GSM8K | 31.40 | 1.00 | 23.50 | 68.00 | 70.60 |
| Safety & Truthfulness | TruthfulQA | 44.70 | 18.20 | 38.00 | 50.30 | 64.80 |
| Safety & Truthfulness | ToxiGen | 52.60 | 46.38 | 41.70 | 42.00 | 55.40 |
| Fairness & Bias | WinoGender | 56.70 | 50.83 | 60.28 | 56.30 | 51.00 |
| Fairness & Bias | CrowS-Pairs | 54.00 | 54.26 | 68.28 | 55.20 | 55.20 |
| Fairness & Bias | BBQ | 79.80 | 38.40 | 55.07 | 38.30 | 59.40 |
A2. Multilingual MMLU, by Language
Accuracy, %.
| Language | BharatGPT-Instruct E2B | BharatGPT-mini 0.5B | Qwen 1.7B | Sarvam 30B |
|---|---|---|---|---|
| Hindi | 41.59 | 23.1 | 34.9 | 32.1 |
| Bengali | 39.22 | 23.9 | 32.3 | 27.4 |
| Marathi | 39.40 | 23.4 | 31.7 | 29.2 |
| Telugu | 38.44 | 23.6 | 30.7 | 25.9 |
| Gujarati | 38.38 | 23.0 | 32.7 | 32.1 |
| Malayalam | 37.96 | 23.2 | 30.9 | 26.3 |
| Punjabi | 37.58 | 23.7 | 31.5 | 25.8 |
| Tamil | 37.30 | 23.5 | 30.9 | 30.1 |
| Odia | 34.82 | 23.9 | 29.8 | 30.3 |
| Kannada | 38.30 | 23.8 | 31.3 | 29.4 |
A3. RAG Evaluation
Scores, %. Grounded in enterprise knowledge-base retrieval, the closest proxy to production chatbot performance.
| RAG Metric | BharatGPT-mini 0.5B | BharatGPT-Instruct E2B | GPT-4o-mini (~8B) | Qwen 3 1.7B |
|---|---|---|---|---|
| Faithfulness | 80.09 | 100.00 | 95.00 | 95.51 |
| Top-K Accuracy | 100 | 100 | 100 | 100 |
| Relevance | 70.95 | 91.07 | 92.12 | 95.76 |
| Recall | 94.1 | 94.12 | 93.07 | 92.51 |
A4. Benchmark Dataset Reference
| Benchmark | What It Tests | Hugging Face Dataset ID | Maintainer |
|---|---|---|---|
| MMLU | Broad domain multitask language understanding | cais/mmlu | Centre for AI Safety (non-profit) |
| HellaSwag | Predicting story/scenario endings, comprehension and creativity | Rowan/hellaswag | Rowan Zellers |
| PIQA | Physical interaction QA, physical commonsense reasoning | baber/piqa | Baber Abbasi |
| WinoGrande | Large-scale coreference resolution (Winograd Schema style) | allenai/winogrande | Ai2 (non-profit) |
| SuperGLUE (BoolQ) | Yes/no QA testing passage comprehension | aps/super_glue | Amanpreet Singh |
| AGIEval | Historical / history-related question tasks | hails/agieval | Hailey Schoelkopf |
| ARC (Easy) | Multiple-choice science QA, basic reasoning and retrieval | allenai/ai2_arc | Ai2 (non-profit) |
| ARC (Challenge) | Multiple-choice science QA, advanced reasoning | allenai/ai2_arc | Ai2 (non-profit) |
| MBPP | Synthesising short Python programs from natural language | google-research-datasets/mbpp | Google Research Datasets |
| GSM8K | Grade-school math word problems, reasoning | openai/gsm8k | OpenAI |
| TruthfulQA | Evaluates truthfulness and factual accuracy of responses | truthful_qa | TruthfulQA |
| ToxiGen | Propensity to generate toxic content | skg/toxigen-data | Toxigen (non-profit) |
| Winogender | Gender-bias diagnostic in coreference resolution | oskarvanderwal/winogender | Oskar van der Wal |
| CrowS-Pairs (Multilingual) | Bias across sociodemographic groups | jannalu/crows_pairs_multilingual | Janna |
| BBQ | Social bias in QA across demographic categories | oskarvanderwal/bbq | Oskar van der Wal |
Disclaimer: Scores reflect the authors' own evaluation runs conducted on standardised public benchmark datasets under consistent experimental conditions. Readers should note that benchmark scores may vary based on evaluation configuration, prompt format, and hardware environment. The authors make no warranties as to completeness or accuracy. Reliance on this data is at the reader's sole discretion.
CoRover: AI with Purpose and Trust.